Claude Fable 5.1 vs GPT-6 Astra: Flagship Smarts, Same $10
Claude Fable 5.1 takes the overall intelligence crown, but GPT-6 Astra fights back hard on long-horizon coding — and both charge the exact same $10.00/1M in, $50.00/1M out. If you live in one model all day, this is the closest real toss-up at flagship tier right now.
Intelligence vs long-haul coding
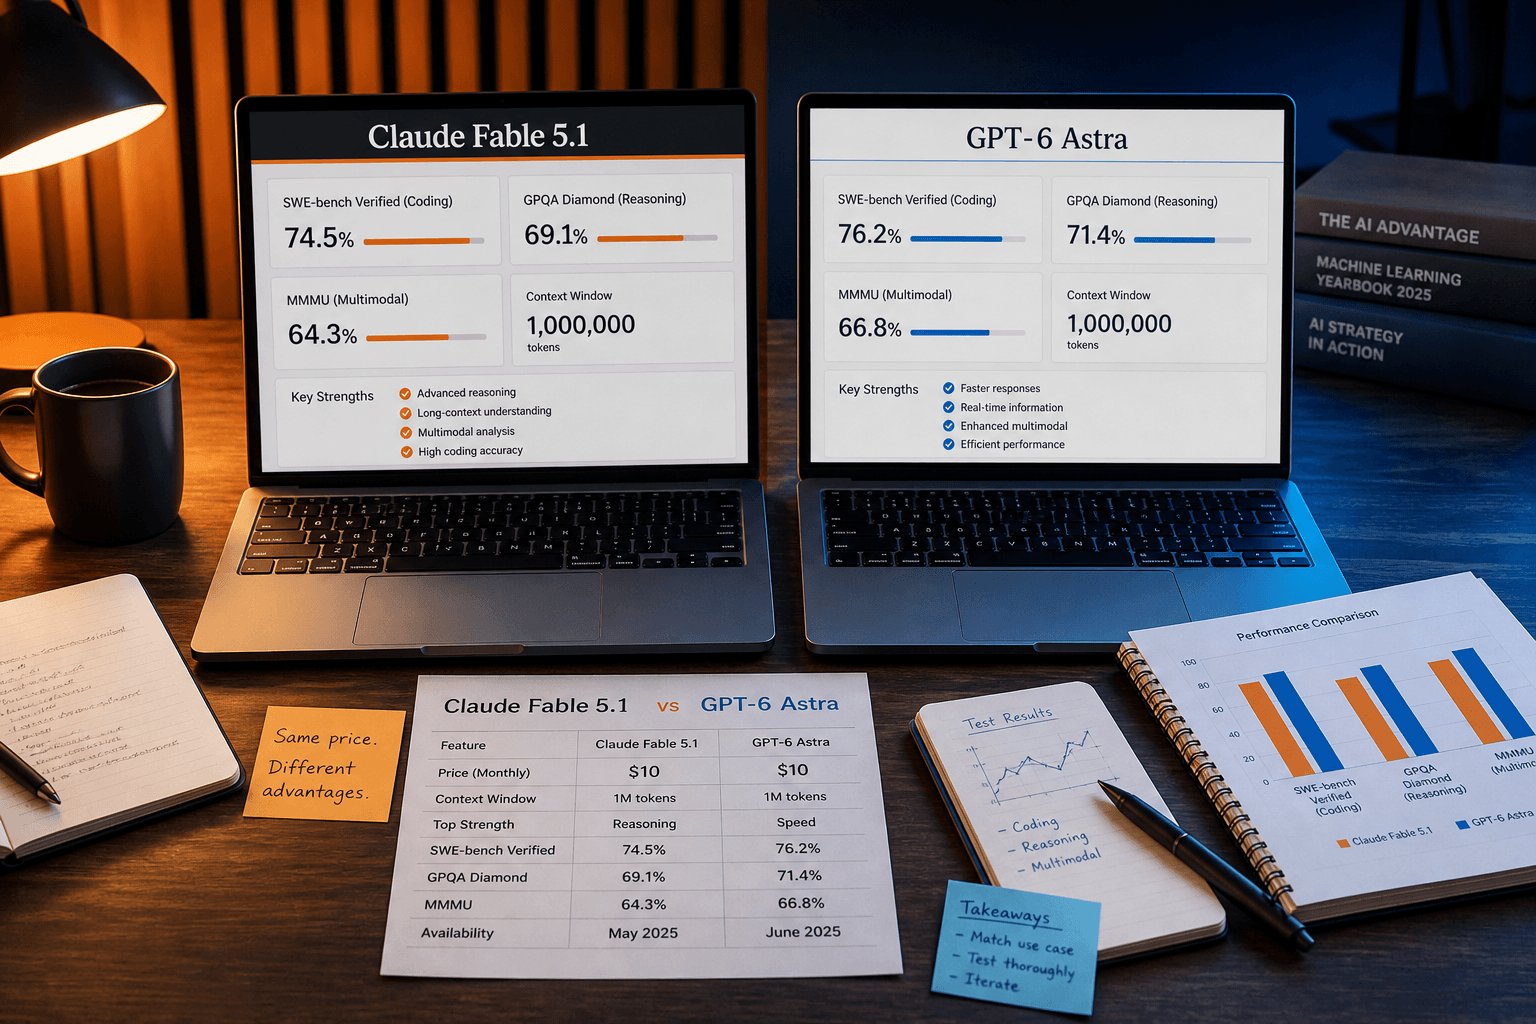
Fable 5.1 posts a 66 on the overall intelligence index, five points clear of Astra's 61. That gap shows up in messy reasoning, nuanced writing, and tasks where a model has to hold a thread. But flip to DeepSWE long-horizon coding and Astra answers with 74.1% — a hair ahead of Gemini 3.8 Flash at 73.8% and well past what Fable's generalist score suggests. Short SWE-Bench sprints don't settle it either: seven models clear 95%, so the top is crowded.
Same sticker price, different spend profile
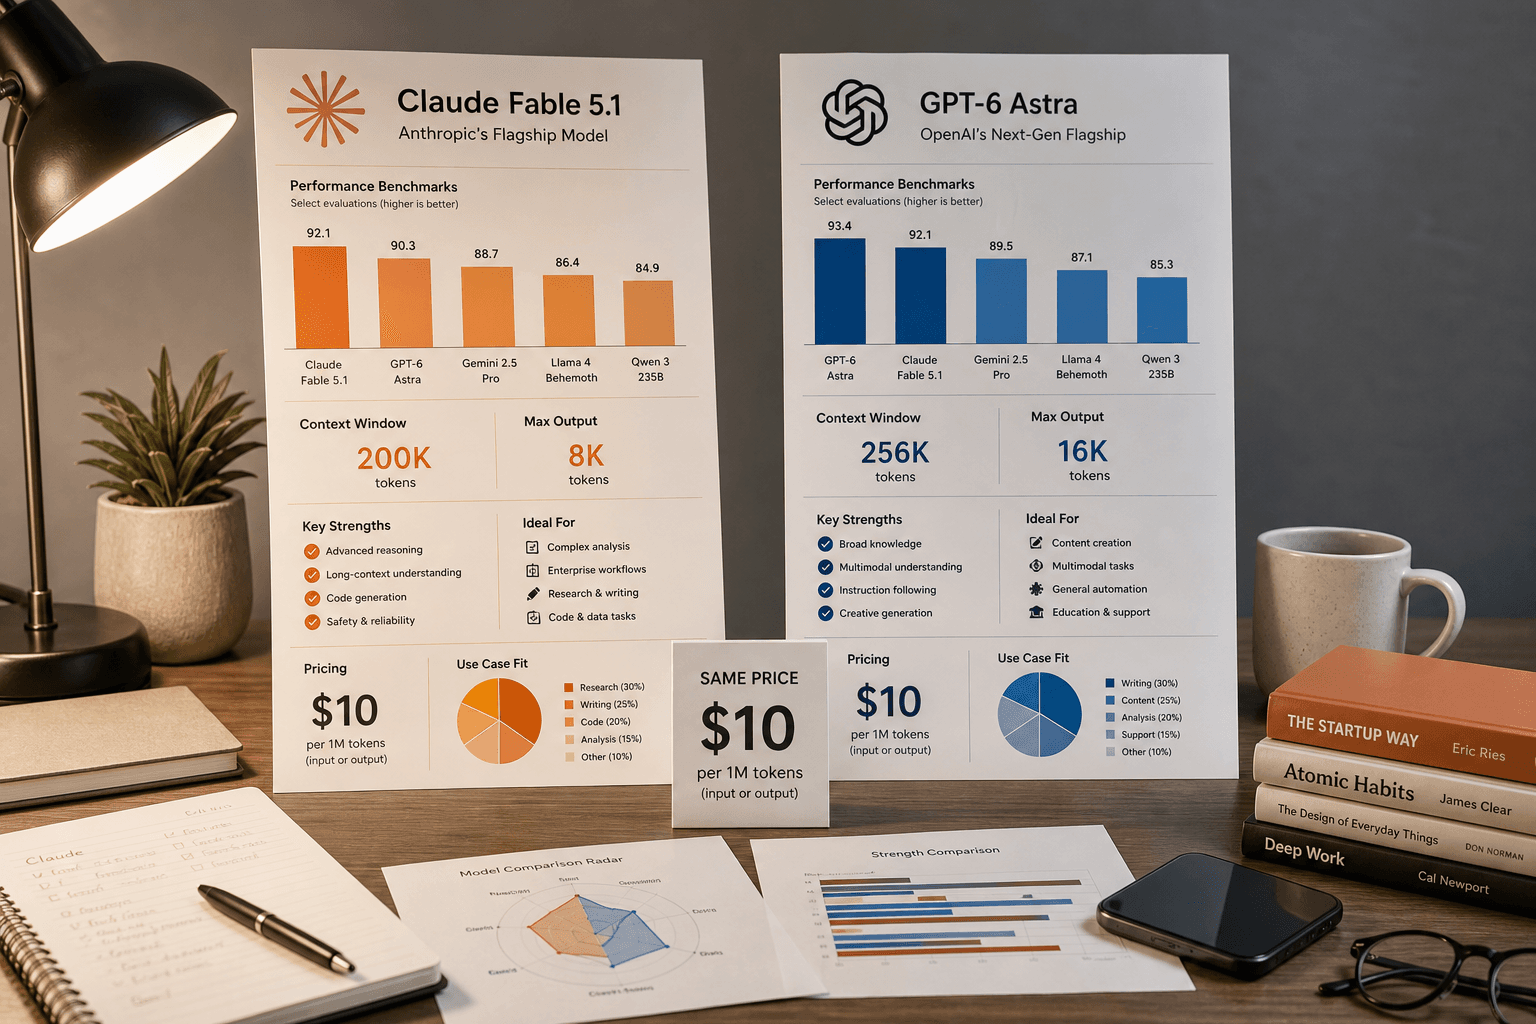
Both models sit at $10.00/1M input and $50.00/1M output, so there's no cost tiebreaker. The real variable is wasted tokens. If your work is deep agentic refactors with long tool chains, Astra's long-horizon edge means fewer restarts and less re-prompting. If your load is analysis, drafting, and mixed reasoning, Fable 5.1's higher intelligence index tends to convert into cleaner first passes — which is its own kind of savings.
Benchmarks aren't a verdict
Astra leads on DeepSWE; Fable leads the index. Neither leads everything, and the supplied snapshot shows rankings shifting by task, date, and configuration. Verify on your own workload before committing.
Verdict: which one should you pick?
Pick Claude Fable 5.1 if you want the strongest general reasoning brain at the $10 tier. Pick GPT-6 Astra if your days are mostly long coding and agentic marathons — it's the specialist that keeps pace overall while winning where you actually sweat.