Claude Fable 5.1 vs GPT-6 Astra: Same Price, Different Brains
If you're choosing between Claude Fable 5.1 and GPT-6 Astra, the short verdict is: Fable 5.1 wins on raw benchmark score, but Astra has the stronger coding reputation right now. Both cost the same, so your call comes down to what you actually need. Neither is a bad pick, but they're not interchangeable.
Benchmark score
On the Artificial Analysis index, Claude Fable 5.1 lands at 66, while GPT-6 Astra sits at 61. That five-point gap isn't huge, but it's consistent across the snapshot. Astra shares the 61 mark with Meta Muse Spark 1.3, so Fable has a genuine general-purpose edge. If you want the model with the higher overall score on paper, Fable 5.1 takes it.
Coding and agentic work
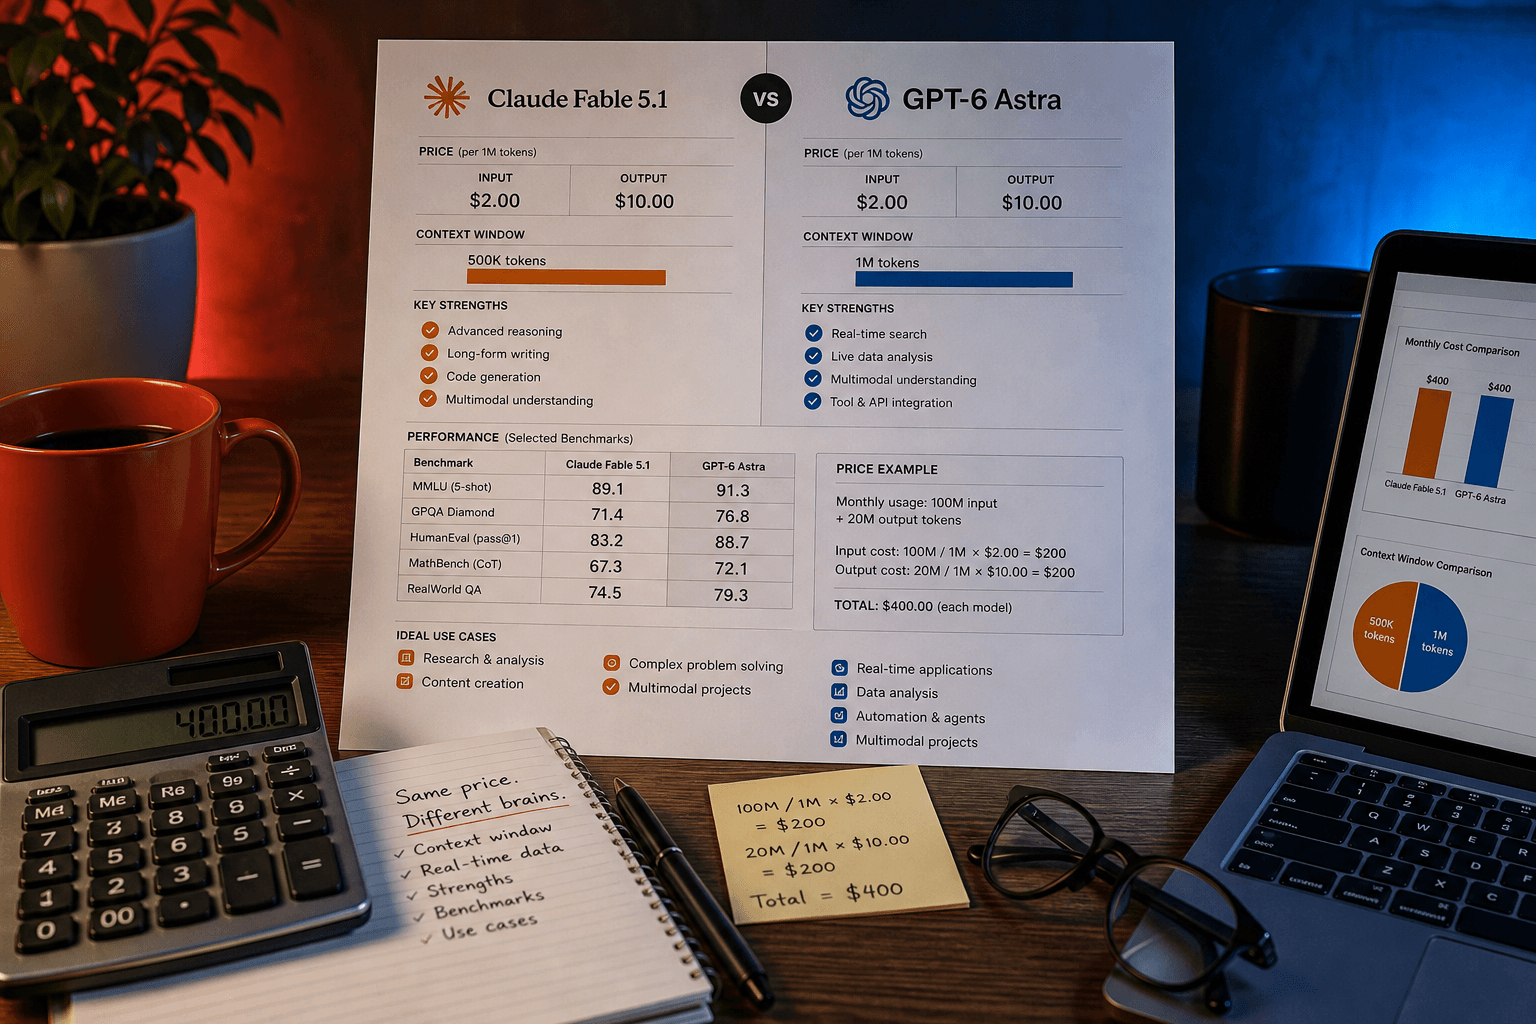
Astra pulls ahead when the task is code. It scores 74.1% on DeepSWE, with Gemini 3.8 Flash close behind at 73.8%. There's no DeepSWE number for Fable 5.1 in the data I have, so I can't say Fable loses head-to-head — only that Astra has the proven coding result. If you're shipping software all day, that benchmark matters more than a general index score. For conversational work, writing, or broad reasoning, Fable 5.1 is the safer bet.
Price
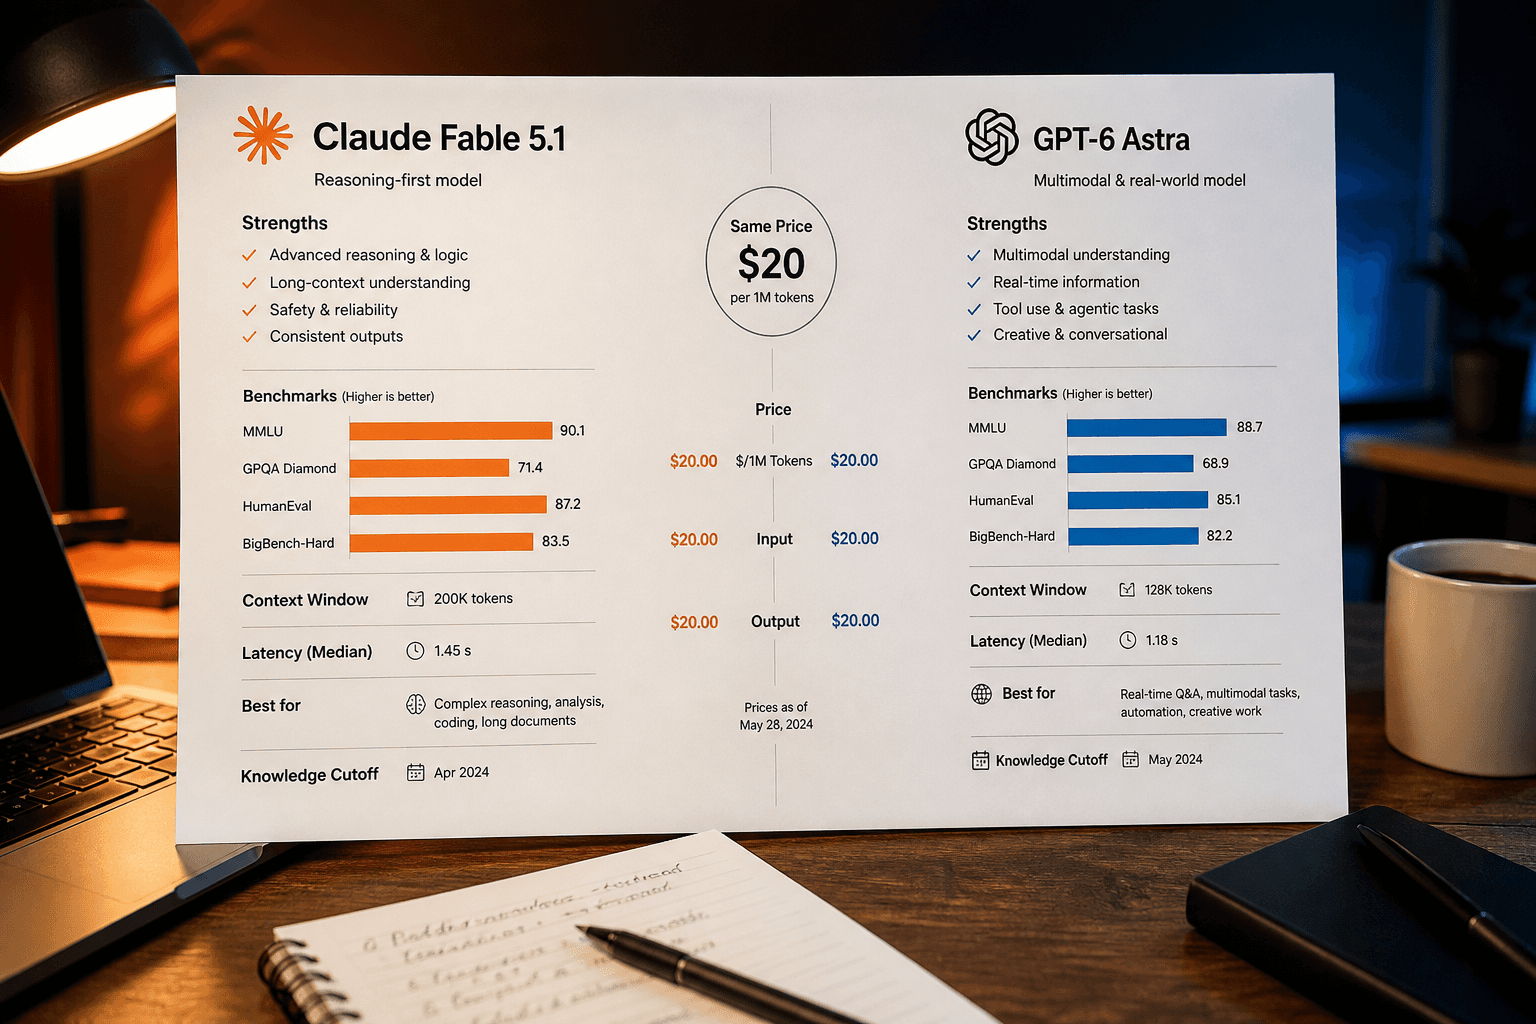
Both models are priced identically: $10.00 per 1M input tokens and $50.00 per 1M output tokens. That makes price a tie and throws the decision fully onto performance and workflow fit. You get no discount for picking either one, so the real question is whether you trust the aggregate benchmark or the specific coding result.
Verdict: which one should you pick?
Pick Claude Fable 5.1 if you want the stronger all-around benchmark score at the same price. Pick GPT-6 Astra if you're a developer who wants the model with a documented coding advantage. If you're on a mixed workload, run your own tests — a five-point index gap and a single coding benchmark won't settle everything.